Products overview
Operate AI factories
with greater intelligence
and control
Move from reactive workflows to proactive operations through continuous infrastructure analysis and optimization.
Benefits
Maximize compute capacity.
Reduce operational risk.
Scale AI factory operations.

Diagnose issues in seconds, not hours

Reduce thermal instability under dynamic workloads

Increase usable compute capacity per MW

Scale operations without additional headcount
Products
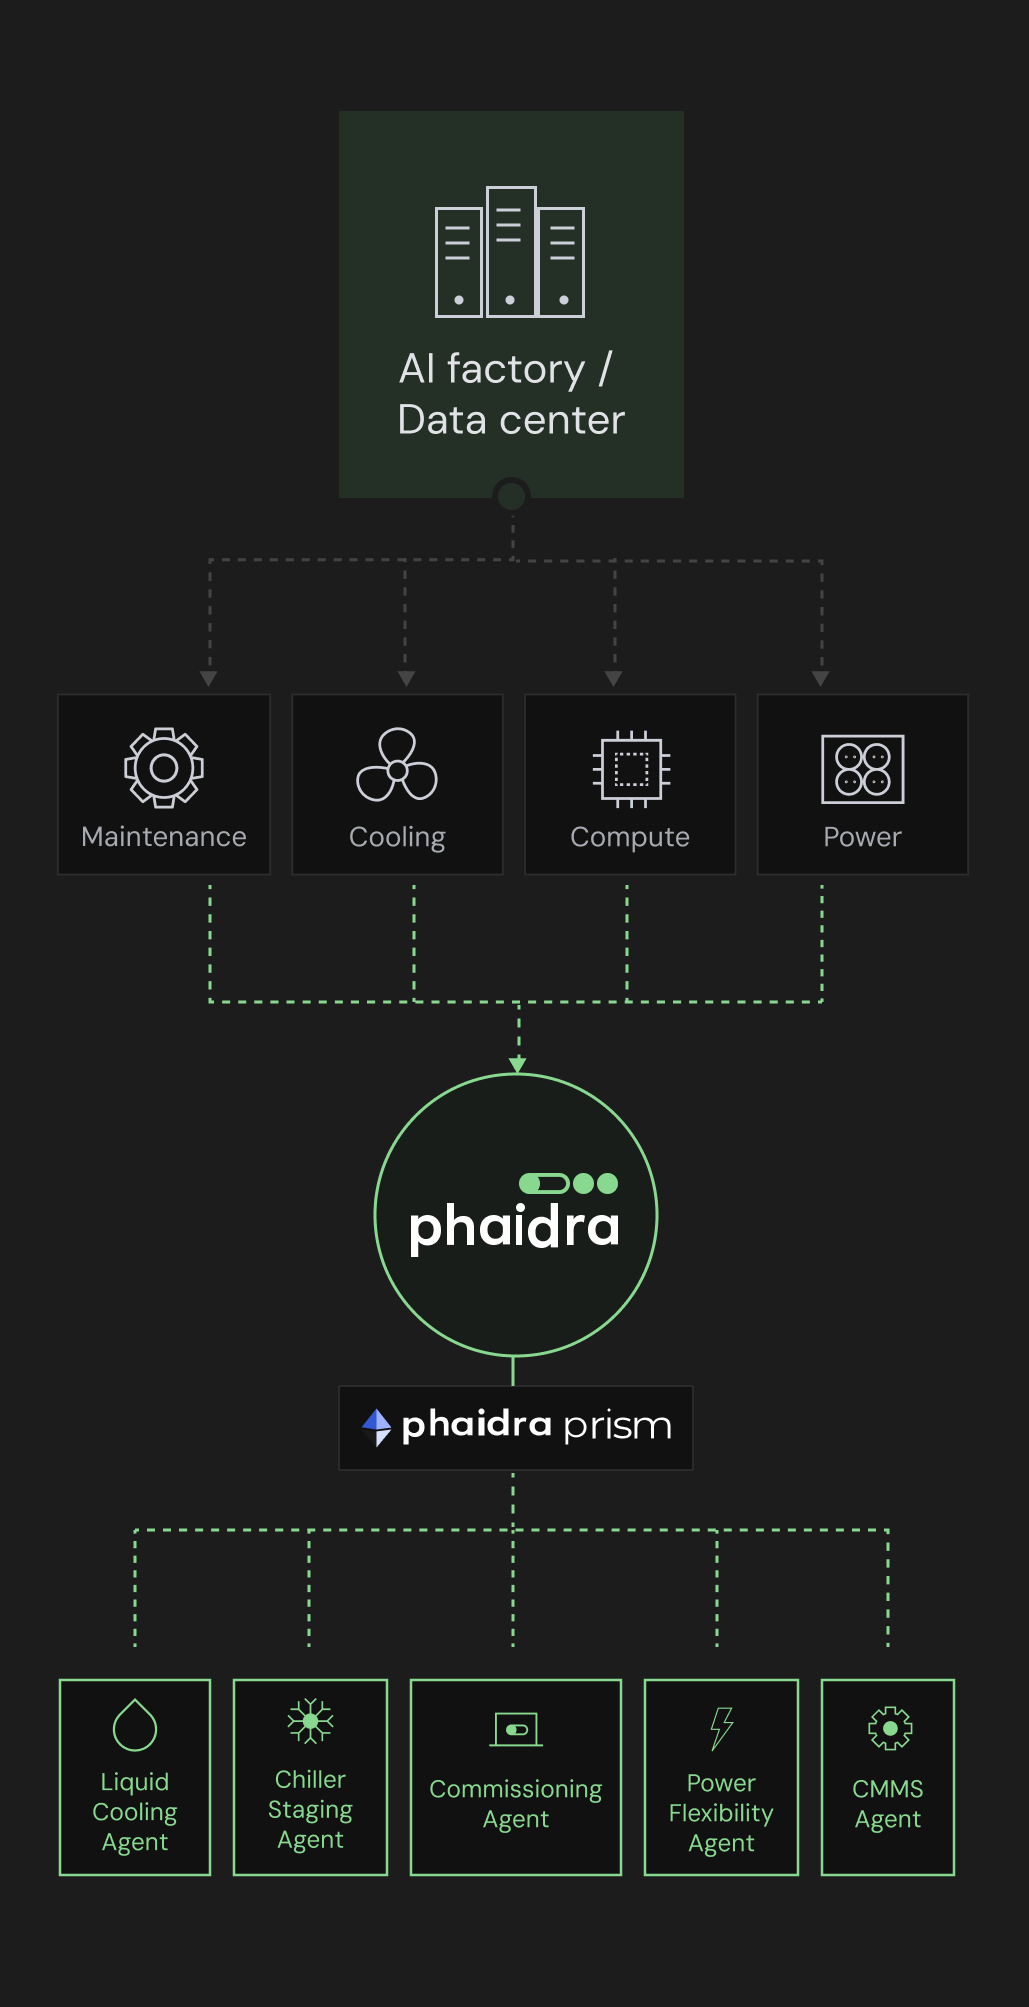
A unified control plane for AI factories
Phaidra Prism
Start with intelligence & observability
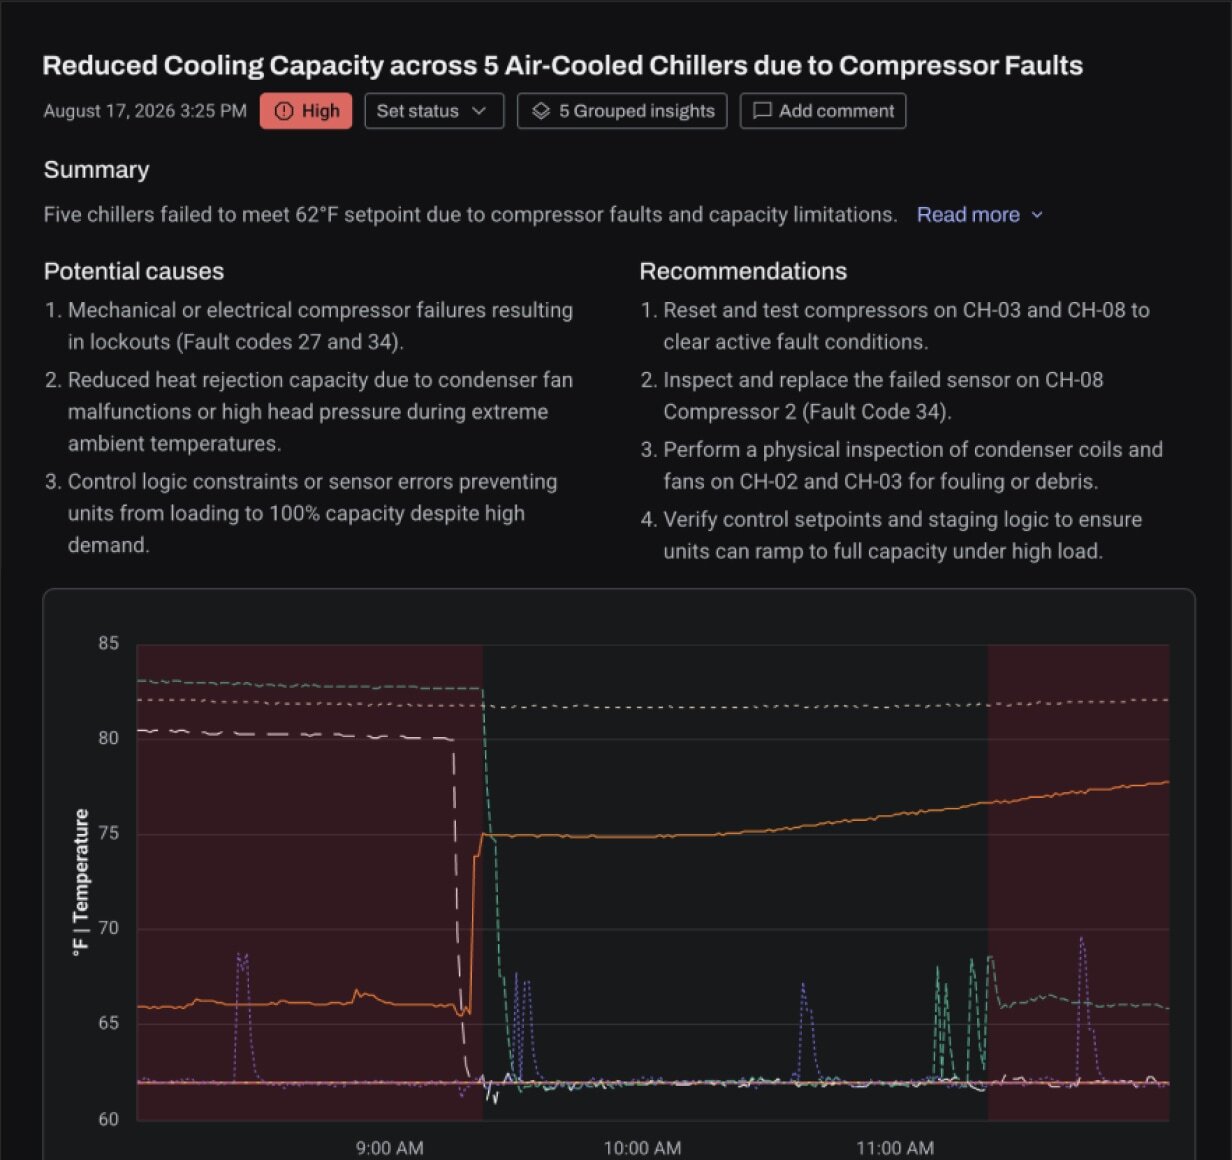
Prism continuously analyzes infrastructure behavior across compute, power, and cooling systems to help operators identify:
-
 Operational drift
-
 Thermal instability
-
 Root cause
-
 Constraint conditions
-
 Correlated infrastructure events
 Operational drift
 Thermal instability
 Root cause
 Constraint conditions
 Correlated infrastructure events
Instead of navigating dashboards and alarm floods, operators receive contextual operational analysis explaining what changed, why it matters, and the recommended actions to resolve the issue.
AI Agents
Move to real-time orchestration
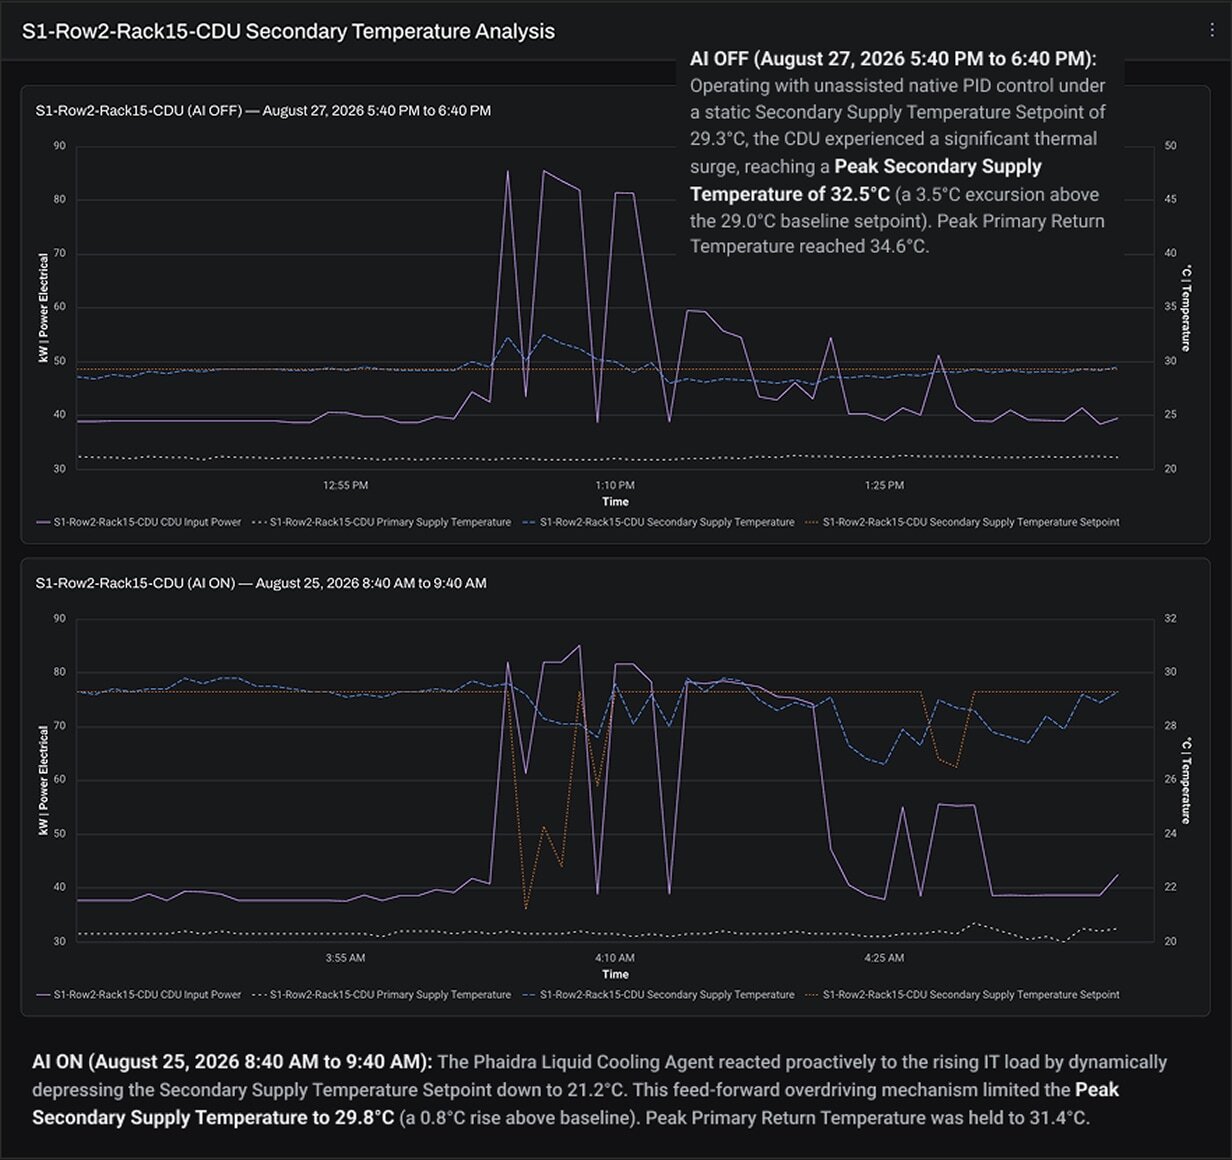
Phaidra’s AI Agents build on Prism’s operational understanding to coordinate infrastructure decisions in real time. Starting with the Liquid Cooling Agent, Phaidra enables operators to:
-
 Prevent GPU throttling
-
 Maintain thermal stability
-
 Eliminate stranded power
-
 Dynamically optimize cooling systems
 Prevent GPU throttling
 Maintain thermal stability
 Eliminate stranded power
 Dynamically optimize cooling systems
How it works
Continuous intelligence across the AI factory
Phaidra builds a living operational model of your unique facility, creating a site-specific knowledge graph that continuously learns from your infrastructure.
Step 1
Connect infrastructure systems
Step 2
Build a unified system-level operational model
Step 3
Continuously analyze infrastructure behavior
Step 4
Optimize infrastructure in real time
Understand
Decide
Act
Learn